人工智能Swift
SwiftAI
纯 Swift 实现的机器学习:在设备上训练、评估并保存模型。
9星标数最新版本: v2.0.0更新时间: 2026年10月15日
支持平台:iOS 15macOS 12tvOS 15watchOS 8visionOS 1
许可证: MIT
SwiftAI 是一个面向 Apple 平台经典机器学习的 Swift package:对数值表格数据做分类、回归、聚类和降维。你可以从 CSV 或数组加载数据,拆分数据集,用一次函数调用训练模型,评估它,并将其保存为 JSON 以便在应用中加载,无需 Python 工具链或服务器。该 package 没有依赖。
功能特性
- 十一种监督模型:线性回归和 ridge 回归、逻辑回归、k-最近邻、高斯朴素贝叶斯、决策树、random forest 和神经网络,外加 k-means 聚类和主成分分析
- 与 scikit-learn 1.9.1 做了比对校验:测试会比较系数、概率和聚类结果(例如逻辑回归的概率精确到 1e-5,PCA 精确到 1e-10)
- 报错而不是崩溃:无效的数据或设置会抛出一个说明该如何修改的 SwiftAIError
- 可安全加载:模型、scaler 和 pipeline 都是 Codable,解码时会检查形状、数值、类别列表和树结构
- 可复现:每个随机步骤都接受一个 seed,相同的 seed 会得到相同的模型,对并行训练的 random forest 也是如此
- Pipeline 只在训练数据上拟合预处理步骤,之后对每个新样本都用同样的方式应用
- 启用严格并发检查的 Swift 6 语言模式;包含四篇文章的 DocC 文档目录,以及面向 iOS 和 macOS 的 ModelLab 示例应用
快速开始
swift
1import SwiftUI2import SwiftAI3 4struct ContentView: View {5 var body: some View {6 Text(irisSummary())7 .padding()8 }9 10 func irisSummary() -> String {11 do {12 // 1. Split the built-in iris flowers into training and test samples.13 let (training, test) = try Dataset.iris.stratifiedSplit(testFraction: 0.2, seed: 42)14 // 2. Train a random forest on the training samples.15 let model = try RandomForestClassifier.fit(training, seed: 42)16 // 3. Measure it on the test samples and classify a new flower.17 let accuracy = try model.accuracy(on: test)18 let species = try model.predict([6.3, 2.8, 5.1, 1.5])19 return "Test accuracy: \(accuracy.formatted(.percent))\nNew flower: \(species)"20 } catch {21 return error.localizedDescription22 }23 }24}安装
Xcode (File › Add Package Dependencies…)
text
1https://github.com/muhittincamdali/SwiftAI.gitSwift Package Manager
swift
1dependencies: [2 .package(url: "https://github.com/muhittincamdali/SwiftAI.git", from: "2.0.0")3],4targets: [5 .target(name: "YourApp", dependencies: [6 .product(name: "SwiftAI", package: "SwiftAI")7 ])8]截图
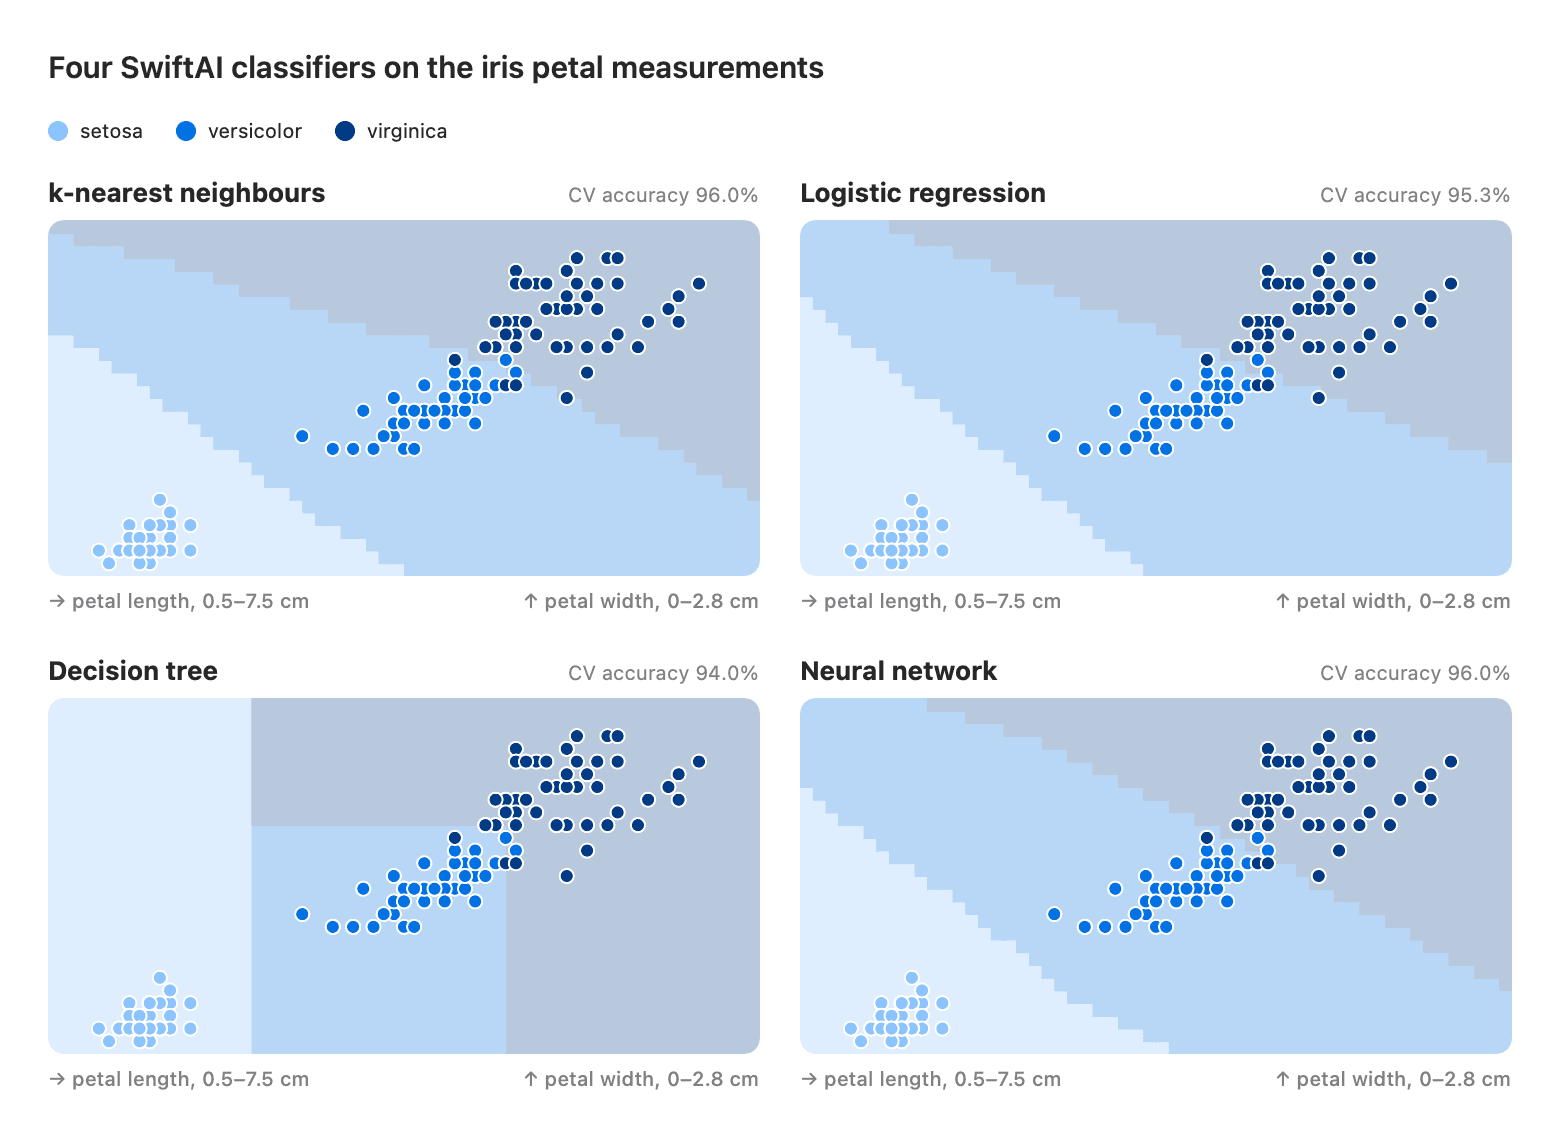
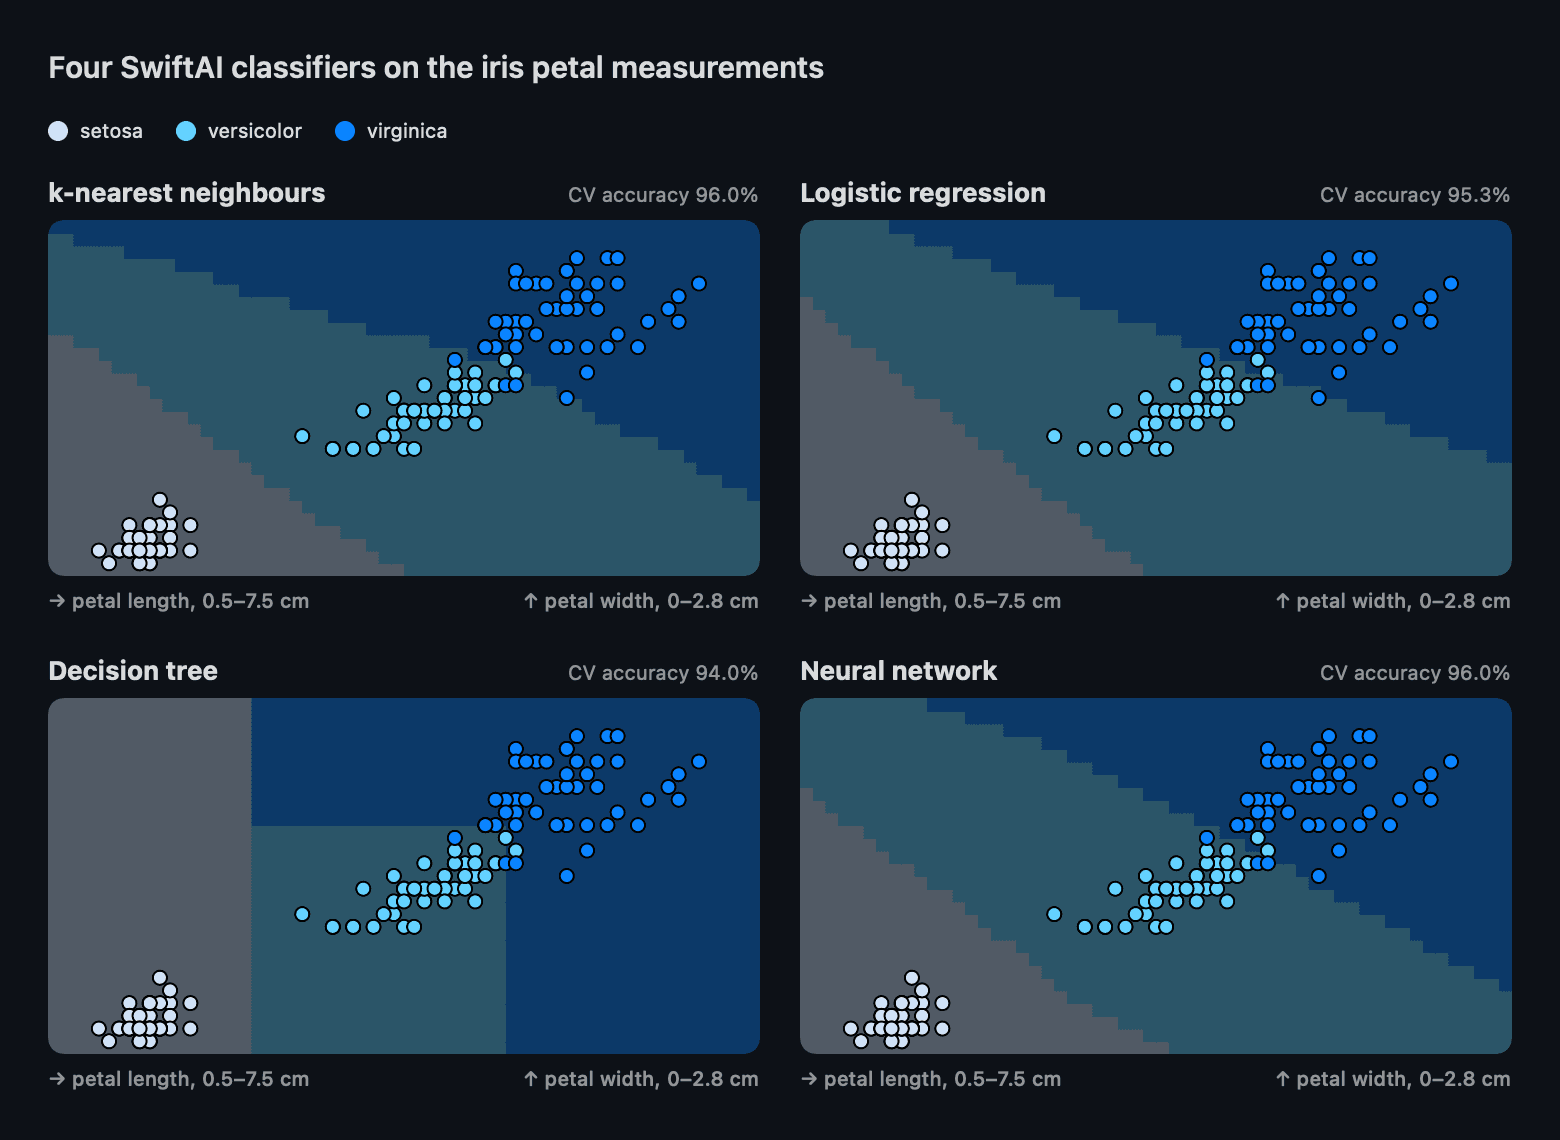
时间线
仓库以一个宽泛的 AI 框架开放,包含应用架构分层以及 Vision 和 NLP 相关代码
发布 1.0.0 版本;三天后移除了应用架构模块,写出了一个更小的机器学习核心
精简:测试缩减为单个占位文件,并加入了一些小型 stub 分层
作为一个无依赖的经典机器学习 package 从头重建,并发布为 2.0.0;没有保留任何 1.0.0 的 API